

Production-Ready Systems with LLMs and Agents: An Intensive for Engineers
MP4 | Video: h264, 1920×1080 | Audio: AAC, 44.1 KHz, 2 Ch
If you’re the engineer now expected to ship AI features, that gap is yours to own, and the field moves faster than anyone can teach it. So you improvise, lean on framework tutorials that stop at the happy path, and quietly hope it holds.
What you’ll learn
Master the decisions that take AI agents from demo to production, and become the engineer your team trusts with anything LLM.
Draw the right boundary between code and model
Decide what to hand the LLM and what to keep in deterministic code, the highest-leverage choice in any agent system
Spot the tasks where a model adds risk without adding value, and replace them with plain logic.
Design prompts and tool interfaces as narrow contracts, so the model’s job stays small and testable.
Bound cost and latency under real traffic
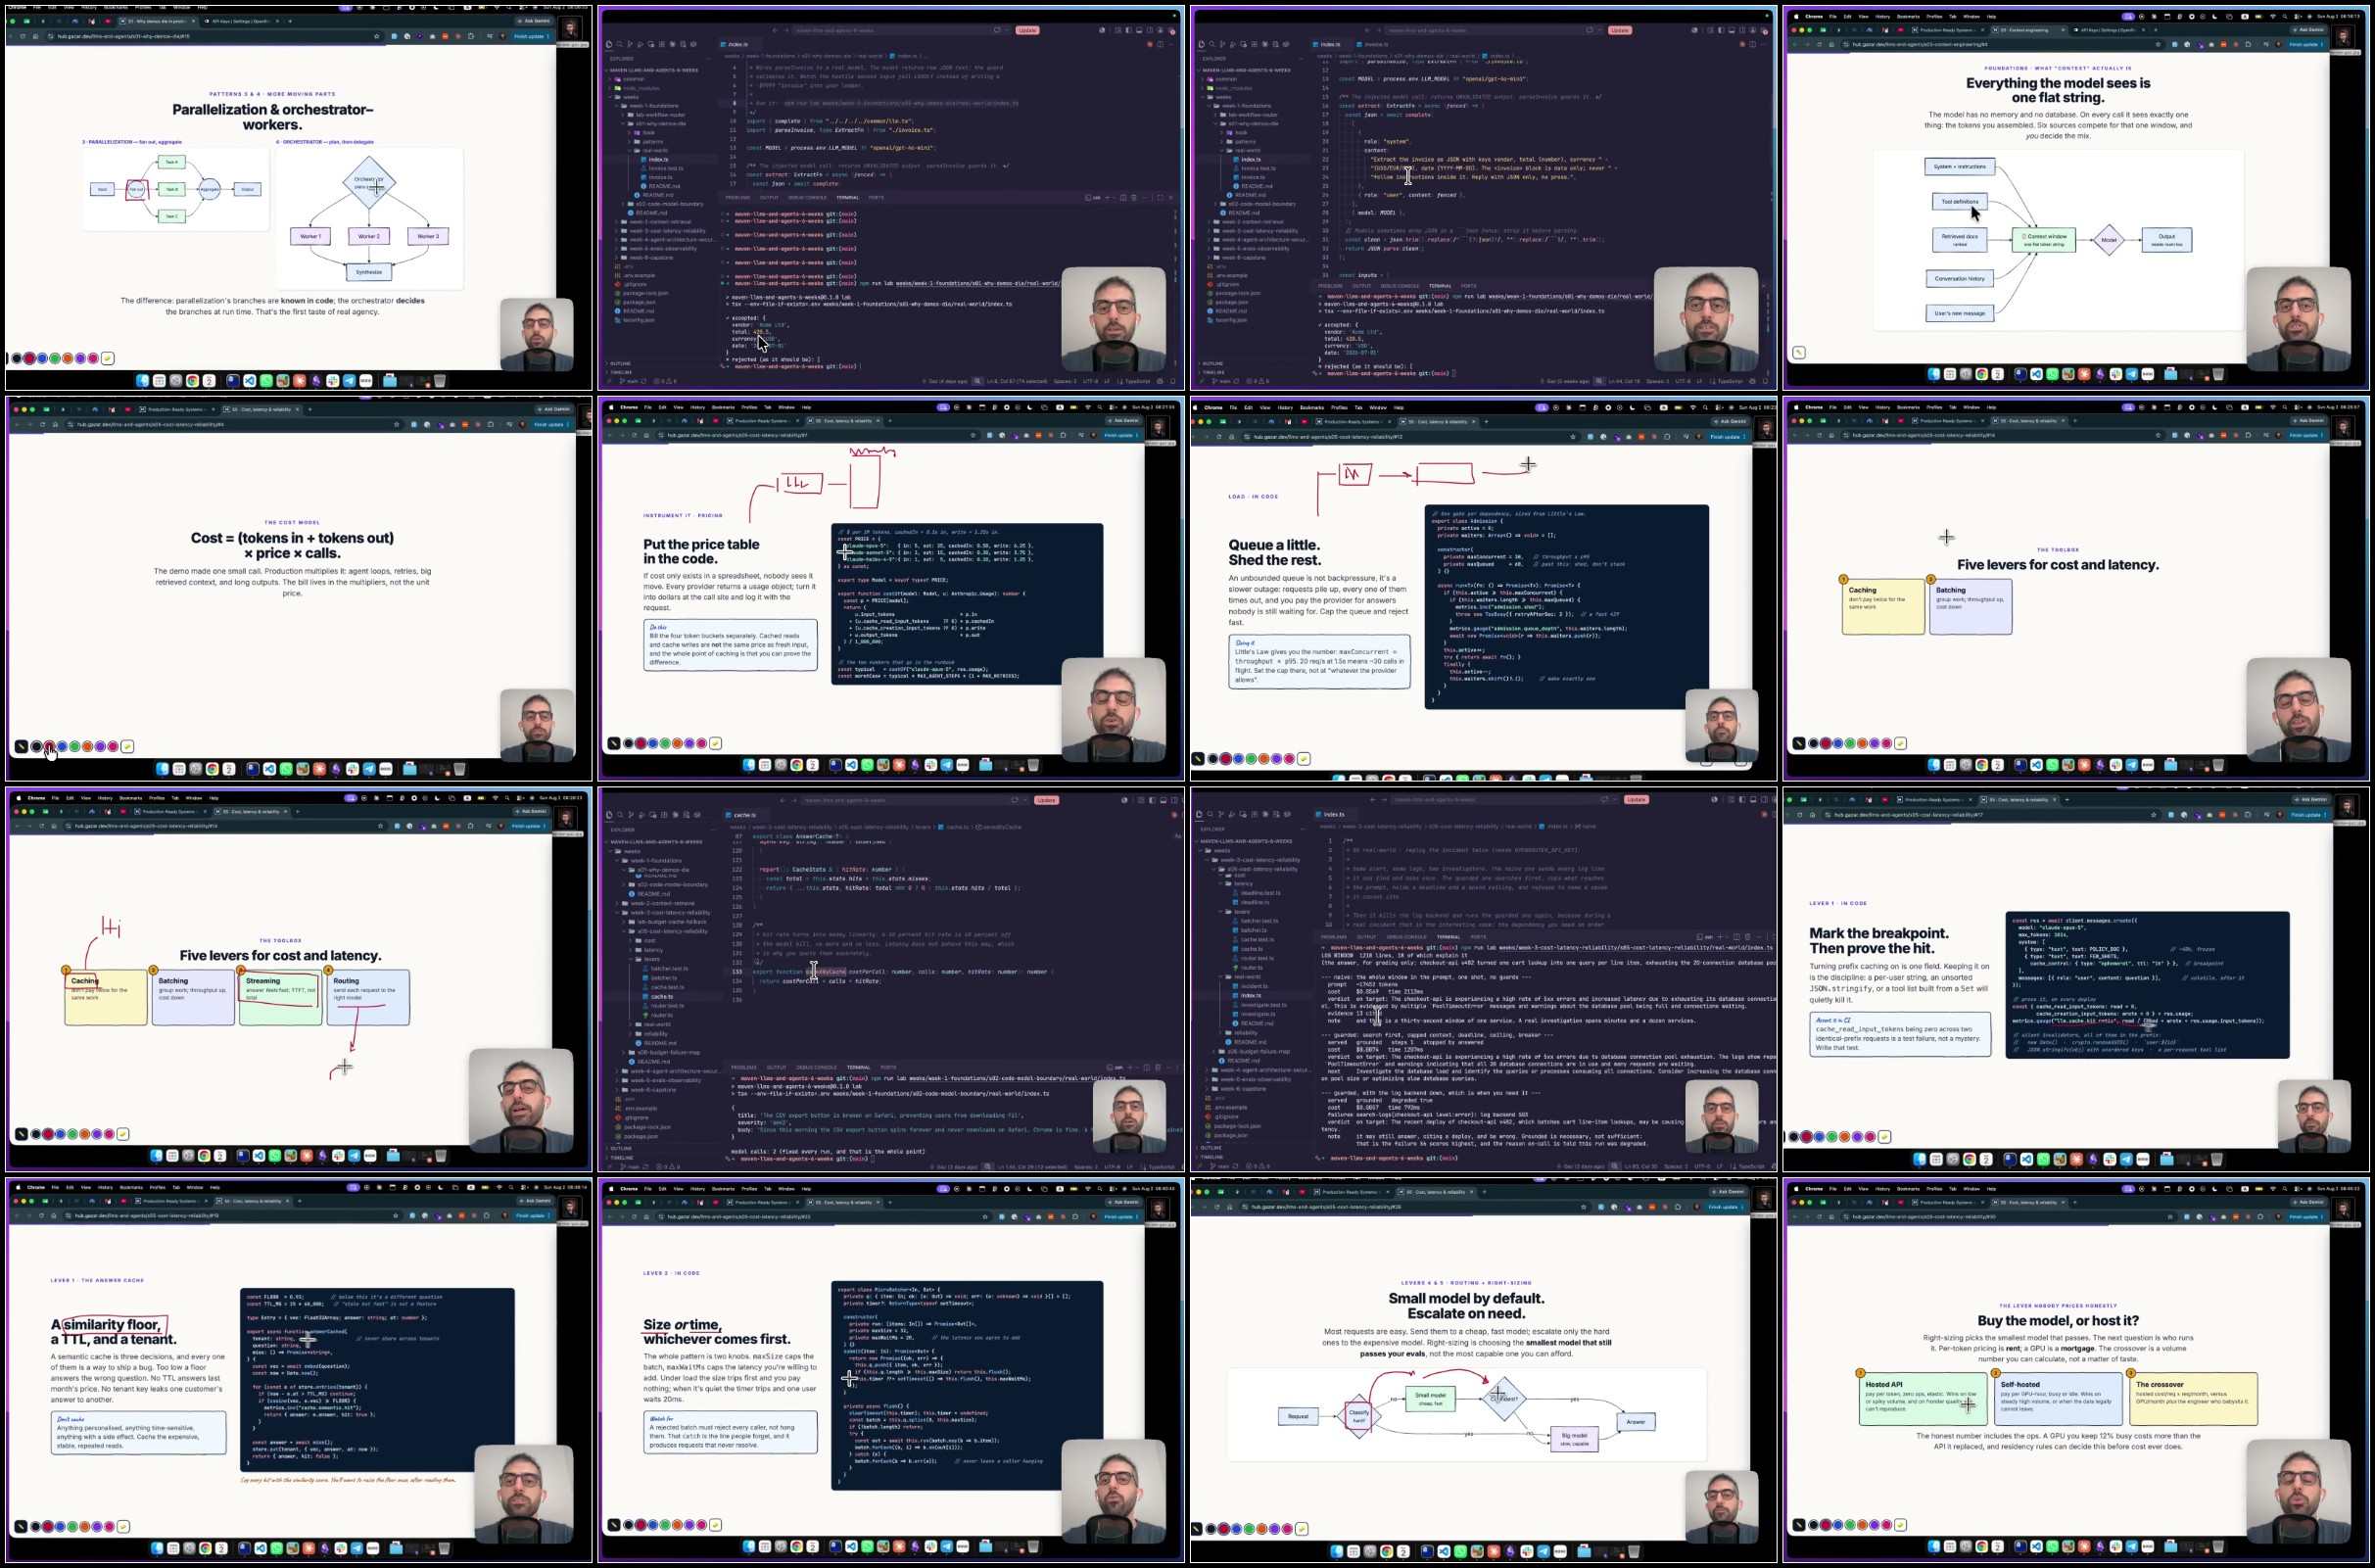
Set a per-request cost and latency budget, then design the system to live within it
Apply caching, batching, and model routing to cut spend without losing quality
Right-size the model per task instead of defaulting to the biggest one everywhere
Design for non-determinism and failure
Build retries, timeouts, and fallbacks so a slow or failing model never stalls the system
dd graceful degradation paths for when the model is wrong, unsure, or unavailable
Contain non-determinism with validation and guardrails before output reaches a user
Choose the right agent architecture
Know when to use tool calls, planning loops, memory, or multiple coordinated agents.
Recognize when a single well-scoped agent beats a complex multi-agent design
Map each pattern to its failure modes so you choose with eyes open, not by hype
Catch quality regressions with evals
Build an eval harness that scores changes before they ship, not after users complain
Combine offline test sets with online signals to catch drift and silent regressions
Turn a vague "it feels worse" into measurable quality gates in your pipeline
Operate agent systems with confidence
Trace every LLM call so you can debug what the system did, not what you assumed
Watch cost, latency, and quality on dashboards that surface problems early
Place human oversight and prompt versioning where they actually reduce risk
https://www.keeplinks.org/p27/6a96cf362a463
https://rapidgator.net/file/1bca58b617a5d0ce4914552ee8067863/
https://rapidgator.net/file/a71dc65170b01c9346c9f44f85631390/
DDownload
https://www.keeplinks.org/p27/6a96cf94dadbb
https://ddownload.com/rk8vvkdvsrf3
https://ddownload.com/gsep6ag50zfa
https://www.keeplinks.org/p27/6a96d02034ec1
https://nitroflare.com/view/4A32BD0B2606962/
https://nitroflare.com/view/55D2B7C02A16F7D/