

Vector Databases & RAG: Build Semantic Search with LLMs
Published 8/2026
MP4 | Video: h264, 1920×1080 | Audio: AAC, 44.1 KHz, 2 Ch
Stop copying RAG code without understanding the retrieval system underneath it.
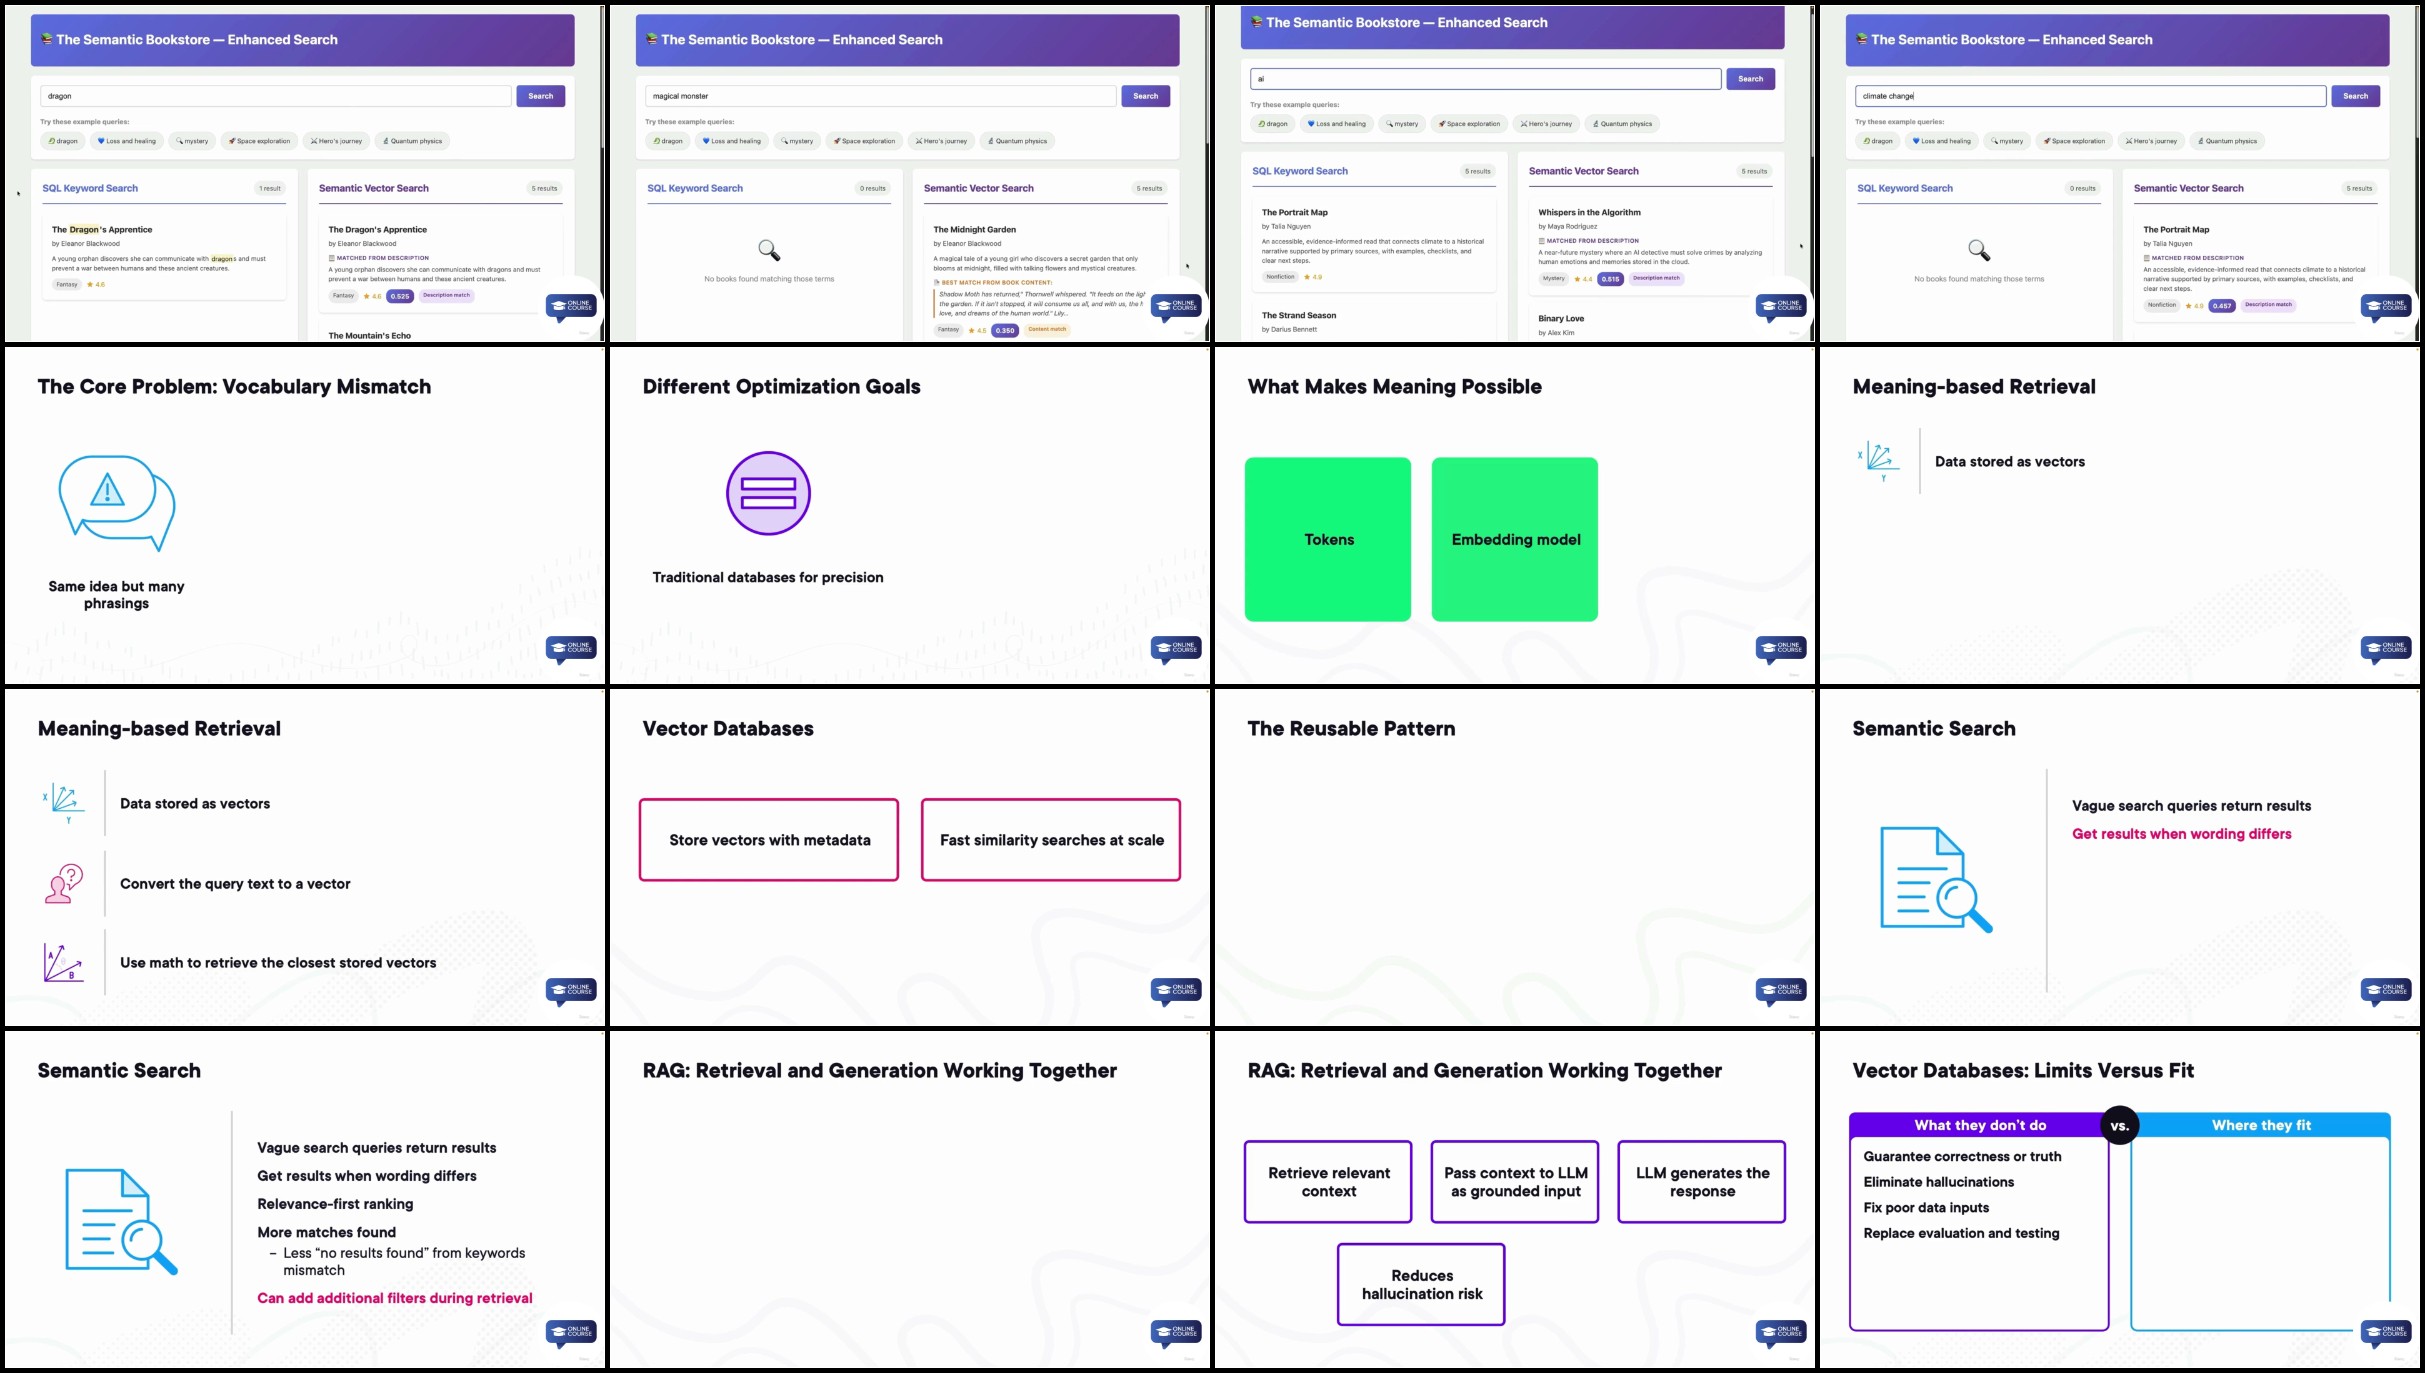
Vector databases are a foundational technology for semantic search, retrieval-augmented generation, recommendations, similarity matching, and other modern AI applications. This course gives you a practical, vendor-neutral introduction to the concepts that make those systems work.
You’ll progress from vectors and embeddings through similarity measurement, nearest-neighbor retrieval, metadata filtering, vector indexes, RAG architecture, database selection, and retrieval evaluation.
Who this course is for:
•
Python and software developers entering AI application development
•
Data and ML engineers new to vector retrieval
•
Developers building semantic search or RAG applications
•
Technical product builders evaluating vector-database technology
•
Students who have followed AI tutorials but want to understand the underlying retrieval architecture
What you will learn:
•
Explain why semantic retrieval uses vector representations
•
Generate and inspect text embeddings
•
Compare cosine similarity, dot product, and Euclidean distance
•
Explain exact and approximate nearest-neighbor retrieval
•
Store vectors with IDs, content references, and metadata
•
Execute top-k semantic searches
•
Apply metadata filters to retrieval
•
Explain how vector retrieval connects to RAG and LLM applications
•
Evaluate retrieval using a repeatable query test set and Recall@K
•
Compare vector-database approaches using technical and operational requirements
Requirements:
Basic Python programming is recommended. Familiarity with APIs and conventional databases will help. No advanced mathematics, machine-learning background, or prior vector-database experience is required.
Final project:
You will build a portfolio-ready semantic retrieval system containing at least 100 records. Your solution will create embeddings, store vectors and metadata, execute top-k similarity searches, support metadata filtering, and undergo evaluation with at least 10 test queries. You will finish with a README, architecture diagram, evaluation results, sample queries, failure analysis, and technology decision that you can discuss with an employer or client.
https://www.keeplinks.org/p27/6a9607da7d6cc
https://rapidgator.net/file/0e8f04bfd78870539b9a882d74317dde/
DDownload
https://www.keeplinks.org/p27/6a96081caa70d
https://ddownload.com/6d7zpg8c8o43
https://www.keeplinks.org/p27/6a96086c4e593
https://nitroflare.com/view/3A7580F32574BAA/
UsersDrive
https://www.keeplinks.org/p27/6a96090adf685